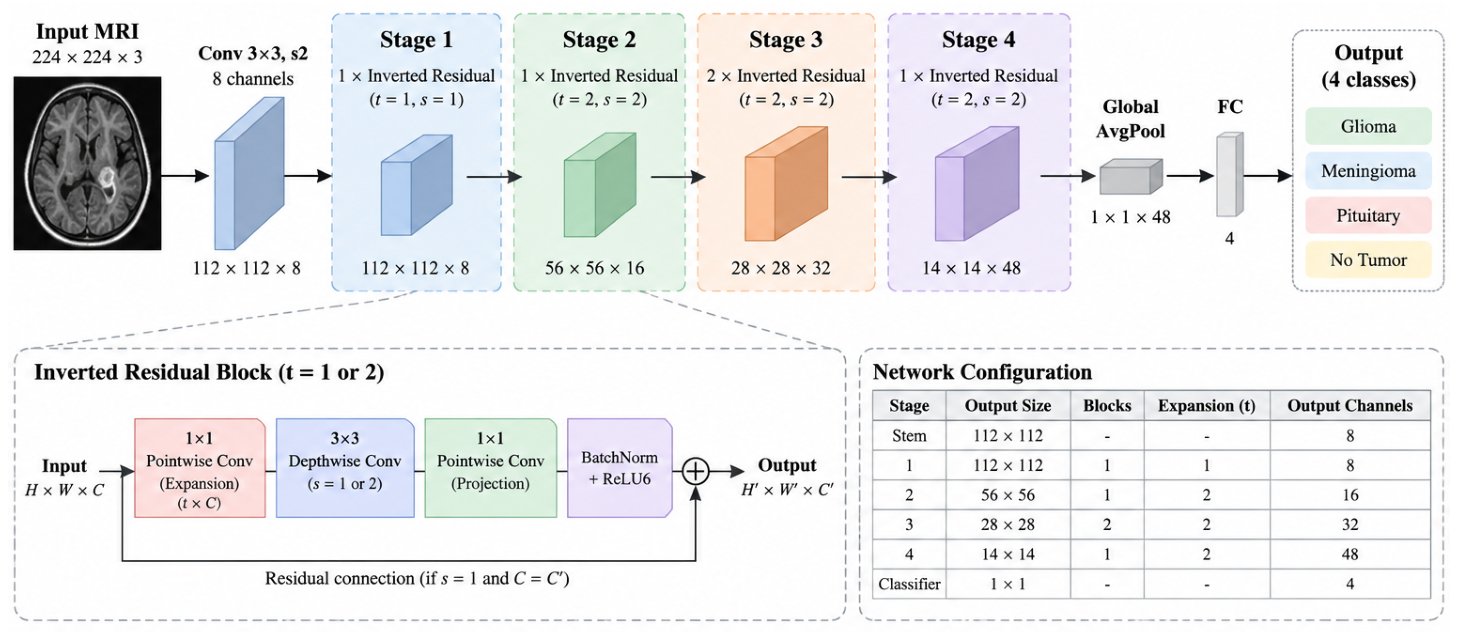
Automated brain tumor classification from magnetic resonance imaging (MRI) can support accessible medical image analysis, but conventional deep learning models often exceed the resource budgets of highly constrained edge-AI platforms. We present NanoNet, an ultra-lightweight convolutional neural network designed for resource-constrained MRI classification and motivated by future edge-AI applications. Inspired by MobileNetV2, NanoNet substantially reduces network depth, channel capacity, expansion ratios, and final feature dimensionality, resulting in only five inverted residual blocks and 8,132 parameters. We further investigate dependency-aware structured pruning, knowledge distillation, and INT8 quantization-aware training for additional compression.
Experiments on the BRISC 2025 benchmark show that NanoNet achieves 92.8% accuracy with 8,132 parameters and 0.0105 GFLOPs. At the same computational cost, it outperforms 70%-pruned MobileNetV2 by 2.9 percentage points while using 58.6% fewer parameters. Its INT8 TensorFlow Lite model requires only 27.7 KB of storage, demonstrating strong potential for future edge-AI deployment.
NanoNet adapts MobileNetV2 inverted residual blocks for a smaller architecture, using five blocks across four stages, eight initial channels, expansion ratios of 1 or 2, and a 48-channel final representation. The compression pipeline then applies dependency-aware structured pruning with distillation fine-tuning, followed by INT8 quantization-aware training.
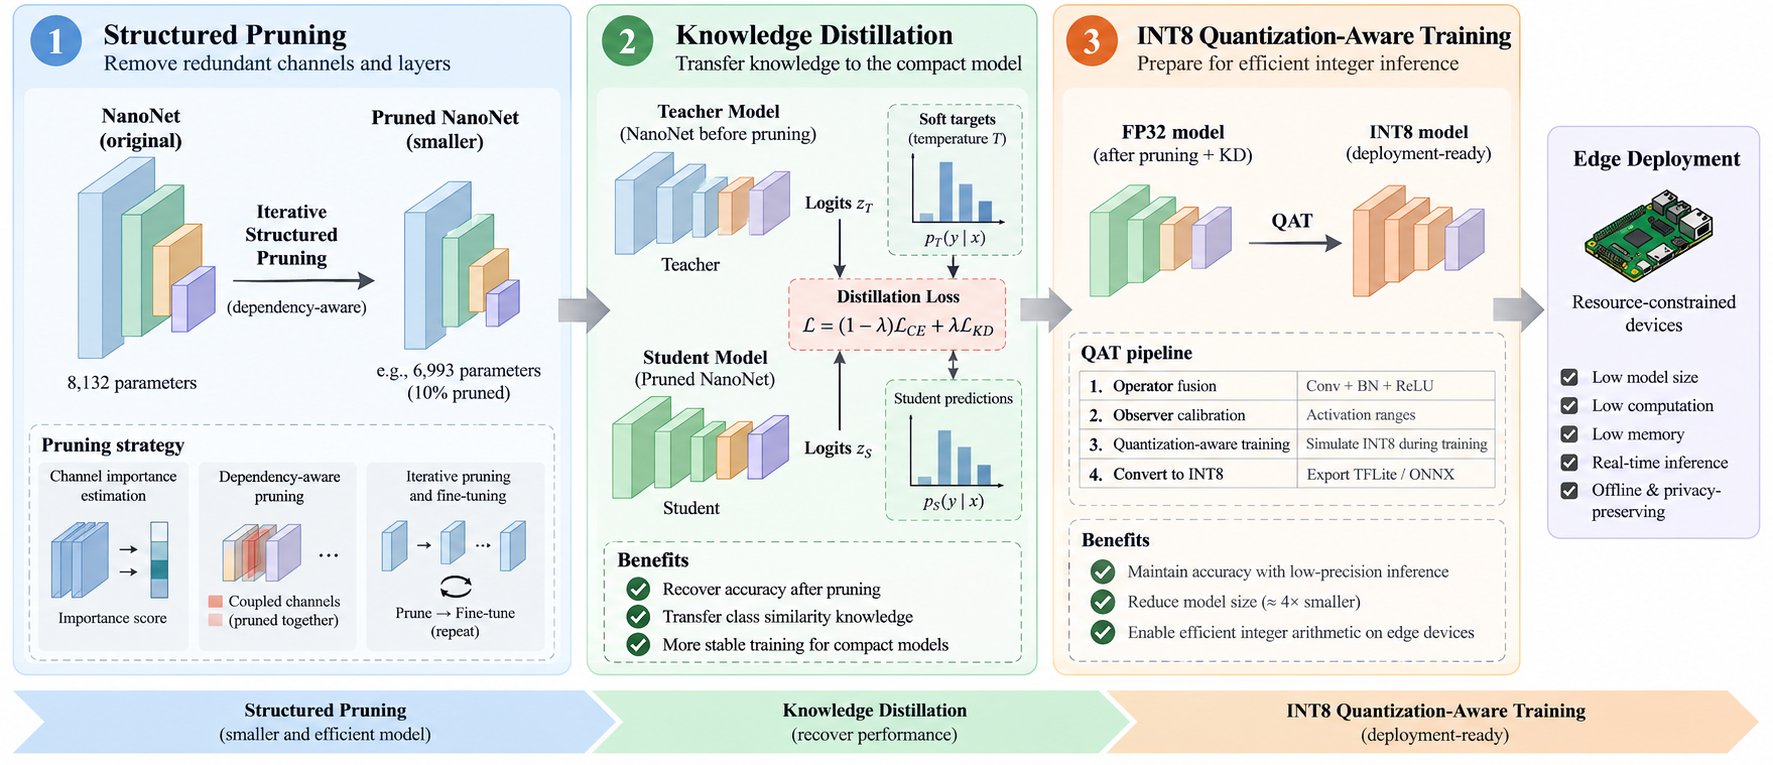
Figure 2. Overview of compression pipeline. The original NanoNet is progressively compressed through dependency-aware structured pruning, knowledge-distillation-based fine-tuning, and INT8 quantization-aware training (QAT), producing a compact model with deployment-oriented resource characteristics.
Table 1. Classification performance and resource characteristics of MobileNetV2 0.1× and NanoNet under structured pruning and quantization-aware training.
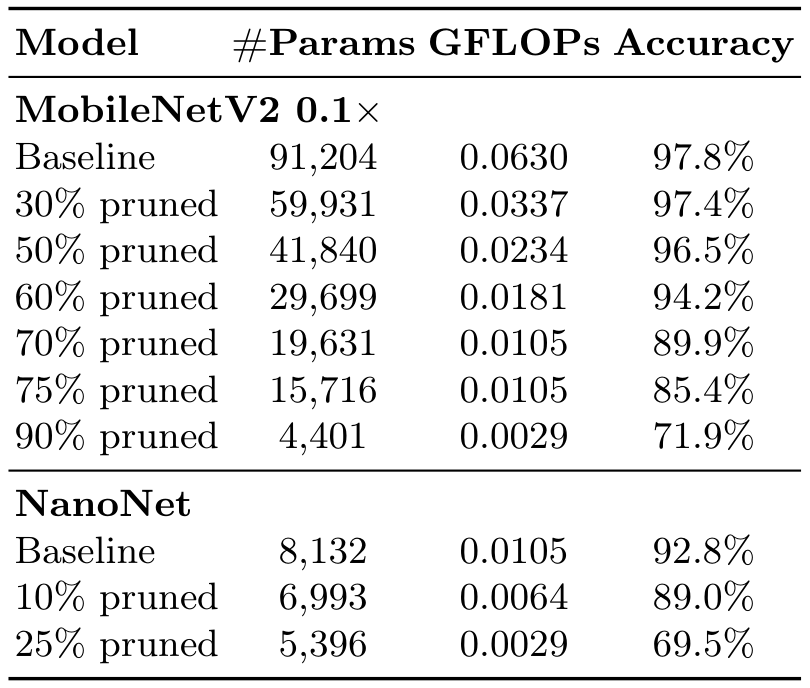
The table shows the accuracy and resource trade-off across pruning levels: NanoNet baseline reaches 92.8% at 0.0105 GFLOPs, compared with 89.9% for 70%-pruned MobileNetV2 at the same compute cost. The paper notes that further pruning NanoNet reduces accuracy, and its experiments cover the BRISC 2025 benchmark rather than cross-dataset generalization.
Table 2. Runtime activation memory and persistent model-storage footprint of selected INT8 models. Peak Tensor Arena represents the maximum TensorFlow Lite runtime memory required during single-batch inference, while Model Storage represents the size of the converted .tflite model.
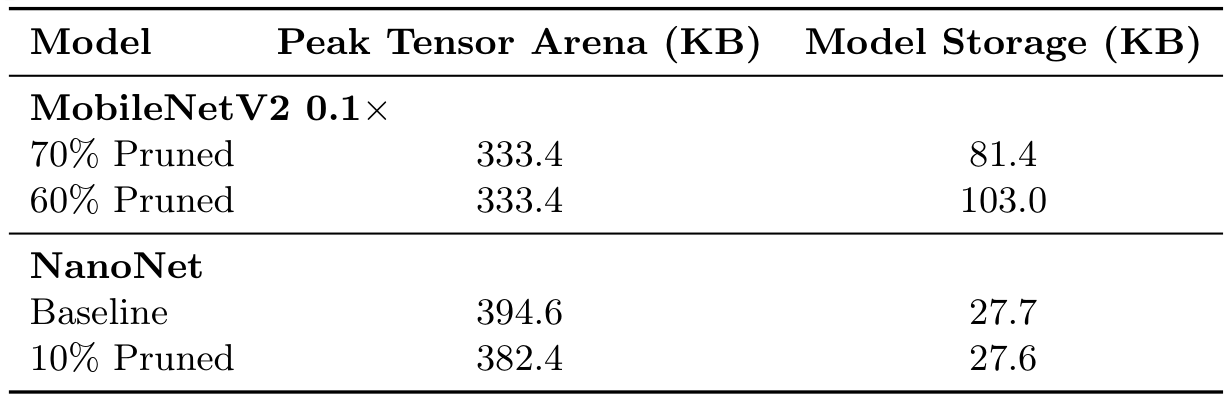
NanoNet baseline has a 27.7 KB model file, compared with 81.4 KB and 103.0 KB for the selected pruned MobileNetV2 models. Peak activation memory is higher for NanoNet at 394.6 KB, compared with 333.4 KB for those MobileNetV2 models; the paper notes these are resource measurements, not physical edge-device performance.
On BRISC 2025, NanoNet reaches 92.8% accuracy at 0.0105 GFLOPs; at that compute cost, 70%-pruned MobileNetV2 reaches 89.9%. The comparison shows NanoNet’s favorable accuracy and parameter count in this low-compute range, while its accuracy drops with further pruning and its activation memory is higher than the selected MobileNetV2 models.
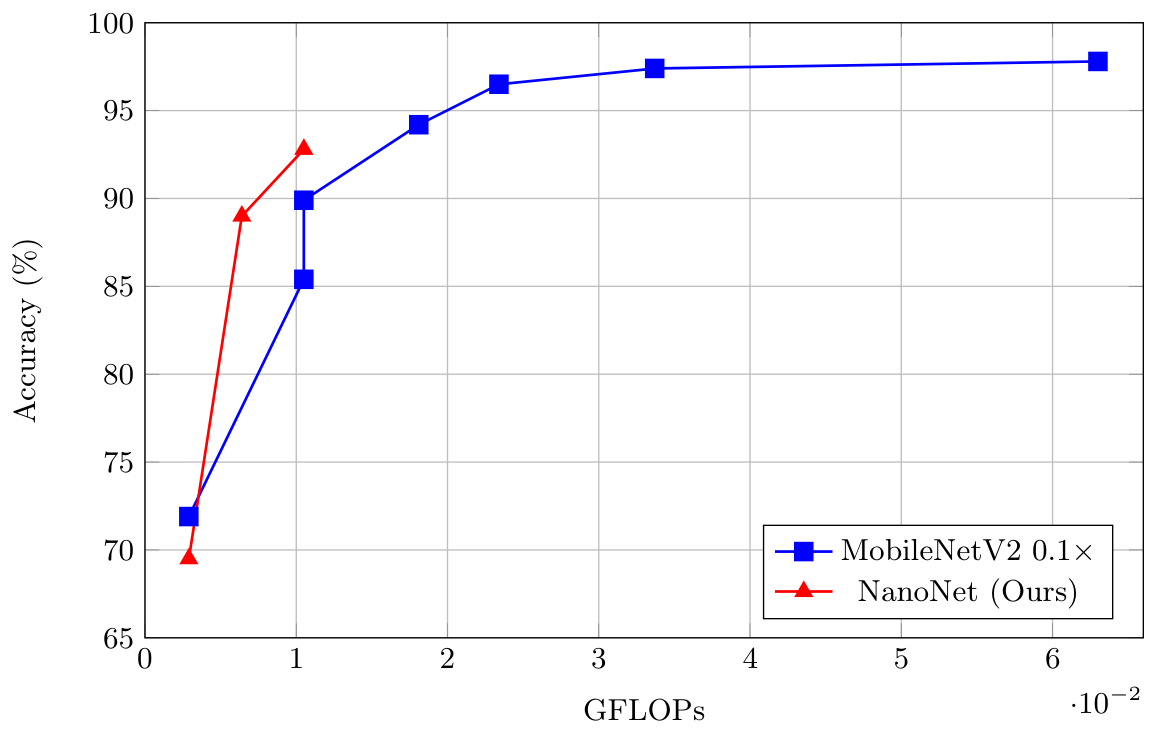
Figure 3. Accuracy-computational-cost trade-off between MobileNetV2 0.1× and NanoNet under different structured-pruning configurations. NanoNet operates in a substantially lower computational regime and provides a competitive accuracy operating point under extreme resource constraints.
@misc{nguyennanonet,
  author = {Nguyen, Le-Tran and Huynh, Huu-Thuan and Tran, Minh-Triet and Le, Trung-Nghia},
  title  = {NanoNet: Ultra-Lightweight Network for MRI Brain Tumor Classification toward Edge AI},
}